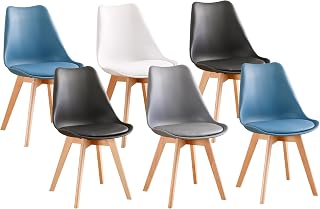
diff --git a/amazon.fr_dump.html b/amazon.fr_dump.html new file mode 100644 index 0000000..dab68f3 --- /dev/null +++ b/amazon.fr_dump.html @@ -0,0 +1,19490 @@ + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + +Amazon.fr : chaise + + + + + + + + + + + + + + + + + +
+ + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + +
+ + +
\ No newline at end of file diff --git a/app/alembic/versions/merge_search_and_catalog.py b/app/alembic/versions/merge_search_and_catalog.py new file mode 100644 index 0000000..f7fac3d --- /dev/null +++ b/app/alembic/versions/merge_search_and_catalog.py @@ -0,0 +1,21 @@ +"""merge search and catalog + +Revision ID: merge_search_and_catalog +Revises: add_search_sites_columns, d2e3f4g5h6i7 +Create Date: 2025-11-30 23:00:00.000000 + +""" +from alembic import op +import sqlalchemy as sa + +# revision identifiers, used by Alembic. +revision = 'merge_search_and_catalog' +down_revision = ('add_search_sites_columns', 'd2e3f4g5h6i7') +branch_labels = None +depends_on = None + +def upgrade() -> None: + pass + +def downgrade() -> None: + pass diff --git a/app/core/search_config.py b/app/core/search_config.py index cde55ec..2c289ec 100644 --- a/app/core/search_config.py +++ b/app/core/search_config.py @@ -56,9 +56,6 @@ SITE_CONFIGS = { "gifi.fr": { "name": "Gifi", "search_url": "https://www.gifi.fr/resultat-recherche?q={query}", - "product_selector": "a.link", - "product_image_selector": "img.tile-image, img[class*='product'], picture img", - "wait_selector": ".product-tile", "category": "Discount", "requires_proxy": False, }, @@ -66,20 +63,13 @@ SITE_CONFIGS = { "name": "Stokomani", "search_url": "https://www.stokomani.fr/search?options%5Bprefix%5D=last&q={query}", "product_selector": "div.product-card", + "product_title_selector": "h3.product-card__title a", + "product_link_selector": "h3.product-card__title a", "product_image_selector": "div.media-wrapper img, img[class*='product-card__image']", "wait_selector": "div.product-card", "category": "Discount", "requires_proxy": False, }, - "action.com": { - "name": "Action", - "search_url": "https://www.action.com/fr-fr/search/?q={query}", - "product_selector": "a.group[href^='/fr-fr/p/']", - "product_image_selector": "img[loading='lazy'], img[src*='product'], picture img", - "wait_selector": "a.group[href^='/fr-fr/p/']", - "category": "Discount", - "requires_proxy": False, - }, "lafoirfouille.fr": { "name": "La Foir'Fouille", "search_url": "https://www.lafoirfouille.fr/recherche?s={query}", @@ -130,12 +120,21 @@ SITE_CONFIGS = { "lincroyable.fr": { "name": "L'Incroyable", "search_url": "https://www.lincroyable.fr/recherche-query={query}/", - "product_selector": "div.tailleBlocProdNew", + "product_selector": "div.tailleBlocProdNew a", "product_image_selector": "img.imgCoup2coeur, img[class*='product']", "wait_selector": "div.tailleBlocProdNew", "category": "Discount", "requires_proxy": False, }, + "amazon.fr": { + "name": "Amazon", + "search_url": "https://www.amazon.fr/s?k={query}", + "product_selector": "div[data-component-type='s-search-result'] h2 a", + "product_image_selector": "img.s-image", + "wait_selector": "div[data-component-type='s-search-result']", + "category": "E-commerce", + "requires_proxy": False, + }, "bmstores.fr": { "name": "B&M", "search_url": "https://bmstores.fr/module/ambjolisearch/jolisearch?s={query}", diff --git a/app/models.py b/app/models.py index f988b22..f76226a 100644 --- a/app/models.py +++ b/app/models.py @@ -94,7 +94,7 @@ class SearchSite(Base): is_active: bool = Column(Boolean, default=True) # type: ignore priority: int = Column(Integer, default=0) # type: ignore # Ordre d'affichage requires_js: bool = Column(Boolean, default=False) # type: ignore # Force Browserless si True - debug_enabled: bool = Column(Boolean, default=False) # type: ignore # Activer le dump HTML pour ce site + debug_enabled: bool = Column(Boolean, default=False, nullable=False) # type: ignore price_selector: str | None = Column(String, nullable=True) # type: ignore # Sélecteur CSS pour le prix search_url: str | None = Column(String, nullable=True) # type: ignore # URL de recherche avec {query} placeholder product_link_selector: str | None = Column(String, nullable=True) # type: ignore # Sélecteur CSS pour les liens produits diff --git a/app/routers/auth.py b/app/routers/auth.py index f9efc42..3511627 100644 --- a/app/routers/auth.py +++ b/app/routers/auth.py @@ -253,3 +253,18 @@ def admin_change_user_password( logger.info(f"Admin '{admin_user.username}' changed password for user '{user.username}'") return {"message": "Mot de passe modifié avec succès"} + + +@router.get("/debug-login") +def debug_login(db: Session = Depends(get_db)): + """ + DEBUG ONLY: Get a valid token for admin user, creating it if necessary. + """ + username = "admin" + user = auth_service.get_user_by_username(db, username) + if not user: + user = auth_service.create_user(db, username, "admin", is_admin=True) + logger.info("Created missing admin user via debug-login") + + token = auth_service.create_token(user.id, user.username, user.is_admin) + return {"token": token, "username": user.username} diff --git a/app/routers/search_sites.py b/app/routers/search_sites.py index 5df10bc..9ae6bff 100644 --- a/app/routers/search_sites.py +++ b/app/routers/search_sites.py @@ -41,17 +41,17 @@ async def update_site( ): """ Met à jour un site de recherche. - Permet uniquement de modifier is_active, priority et debug_enabled. + Permet uniquement de modifier is_active et priority. """ # Limiter les champs modifiables - allowed_fields = {"is_active", "priority", "debug_enabled"} + allowed_fields = {"is_active", "priority"} update_data = site.model_dump(exclude_unset=True) filtered_data = {k: v for k, v in update_data.items() if k in allowed_fields} if not filtered_data: raise HTTPException( status_code=400, - detail="Seuls les champs 'is_active', 'priority' et 'debug_enabled' peuvent être modifiés" + detail="Seuls les champs 'is_active' et 'priority' peuvent être modifiés" ) updated = search_service.update_site(db, site_id, filtered_data) diff --git a/app/schemas.py b/app/schemas.py index e34886c..9e510e1 100644 --- a/app/schemas.py +++ b/app/schemas.py @@ -53,7 +53,7 @@ class SearchSiteCreate(BaseModel): is_active: bool = True priority: int = 0 requires_js: bool = False - debug_enabled: bool = False # Activer le dump HTML pour ce site + # debug_enabled removed price_selector: str | None = None search_url: str | None = None # URL avec {query} placeholder, ex: https://amazon.fr/s?k={query} product_link_selector: str | None = None # Sélecteur CSS pour les liens produits @@ -67,7 +67,7 @@ class SearchSiteUpdate(BaseModel): is_active: bool | None = None priority: int | None = None requires_js: bool | None = None - debug_enabled: bool | None = None # Activer le dump HTML pour ce site + # debug_enabled removed price_selector: str | None = None search_url: str | None = None product_link_selector: str | None = None @@ -82,7 +82,7 @@ class SearchSiteResponse(BaseModel): is_active: bool priority: int requires_js: bool - debug_enabled: bool = False # Activer le dump HTML pour ce site + # debug_enabled removed price_selector: str | None = None search_url: str | None = None product_link_selector: str | None = None diff --git a/app/services/browserless_service.py b/app/services/browserless_service.py index da55a0b..99596f3 100644 --- a/app/services/browserless_service.py +++ b/app/services/browserless_service.py @@ -446,6 +446,15 @@ class BrowserlessService: break except Exception: continue + + # Generic wait selector + if wait_selector: + try: + logger.info(f"⏳ Waiting for selector: {wait_selector}") + await page.wait_for_selector(wait_selector, timeout=10000, state="attached") + logger.info(f"✅ Wait selector found: {wait_selector}") + except Exception as e: + logger.warning(f"⚠️ Wait selector {wait_selector} timed out or failed: {e}") # Extract content if extract_text: diff --git a/app/services/improved_search_service.py b/app/services/improved_search_service.py index 91226ac..2e81071 100644 --- a/app/services/improved_search_service.py +++ b/app/services/improved_search_service.py @@ -175,143 +175,6 @@ class ImprovedSearchService: except Exception: pass - try: - await page.keyboard.press("Escape") - except Exception: - pass - - @classmethod - async def search_site(cls, site_key: str, query: str) -> list[SearchResult]: - """ - Search a single site using persistent browser - - Args: - site_key: Site configuration key - query: Search query - - Returns: - List of SearchResult objects - """ - config = SITE_CONFIGS.get(site_key) - if not config: - logger.error(f"Unknown site: {site_key}") - return [] - - search_url = config["search_url"].format(query=quote_plus(query)) - logger.info(f"🔍 Searching {config['name']} at {search_url}") - - # Retry logic - max_retries = 1 - for attempt in range(max_retries + 1): - try: - # Ensure browser is connected (check before each attempt) - if not await cls._ensure_browser_connected(): - logger.error("Failed to establish browser connection") - if attempt < max_retries: - continue - return [] - - context = await cls._create_context(cls._browser) - try: - page = await context.new_page() - - try: - # Navigate to search page - logger.debug(f"Navigating to {search_url}") - await page.goto(search_url, wait_until="domcontentloaded", timeout=30000) - logger.debug("Page loaded (domcontentloaded)") - - # Wait for network idle - try: - await page.wait_for_load_state("networkidle", timeout=10000) - logger.debug("Network idle reached") - except PlaywrightTimeoutError: - logger.debug("Network idle timed out (non-critical)") - - # Handle popups - await cls._handle_popups(page) - - # Wait for content to load - wait_selector = config.get("wait_selector") - if wait_selector: - try: - await page.wait_for_selector(wait_selector, timeout=5000) - logger.debug(f"Wait selector found: {wait_selector}") - except PlaywrightTimeoutError: - logger.warning(f"Wait selector not found: {wait_selector}") - - # Small delay for JS rendering - await page.wait_for_timeout(2000) - - # Get HTML content - html_content = await page.content() - logger.info(f"✅ Page content extracted ({len(html_content)} bytes)") - - if len(html_content) < 5000: - logger.warning(f"⚠️ Page too small - possibly blocked") - return [] - - # Parse results using specialized parser - parser = ParserFactory.get_parser(site_key) - parsed_products = parser.parse_search_results(html_content, query, search_url) - - # Convert ProductResult to SearchResult - results = [cls._convert_to_search_result(p) for p in parsed_products] - - # Scrape details for each result (in parallel) - if results: - logger.info(f"📦 Found {len(results)} initial results, enriching with details...") - - # Enrich all results - results_to_enrich = results - logger.info(f"⚡ Enriching all {len(results_to_enrich)} products") - - semaphore = asyncio.Semaphore(4) # Increased concurrency slightly - - async def scrape_with_limit(res): - async with semaphore: - return await cls._scrape_item_details(res, context) - - tasks = [scrape_with_limit(r) for r in results_to_enrich] - enriched_results = await asyncio.gather(*tasks) - - # Filter out failed enrichments if any (though scrape_item_details returns original on failure) - results = [r for r in enriched_results if r] - - # If we got here, success! - logger.info(f"✅ Successfully found {len(results)} products from {config['name']}") - return results - - finally: - await page.close() - - finally: - try: - await context.close() - except Exception as e: - logger.debug(f"Error closing context (ignored): {e}") - - except (PlaywrightTimeoutError, Exception) as e: - # Check if it's a connection error or target closed - error_msg = str(e).lower() - is_connection_error = "target closed" in error_msg or "connection" in error_msg or "browser has been closed" in error_msg - - if is_connection_error and attempt < max_retries: - logger.warning(f"⚠️ Connection error during search for {site_key}: {e}. Retrying ({attempt+1}/{max_retries})...") - # Force reconnect - cls._browser = None - await asyncio.sleep(1) - continue - - logger.error(f"❌ Error during search: {e}", exc_info=True) - return [] - - return [] - - @staticmethod - def _convert_to_search_result(product: ProductResult) -> SearchResult: - """Convert ProductResult to SearchResult""" - return SearchResult( url=product.url, title=product.title, snippet=product.snippet, @@ -601,12 +464,6 @@ class ImprovedSearchService: return None # Unknown - @classmethod - async def search_site_generator(cls, site_key: str, query: str) -> AsyncGenerator[SearchResult, None]: - """Search a single site and yield results as they are scraped""" - results = await cls.search_site(site_key, query) - for result in results: - yield result @classmethod async def search_all(cls, query: str) -> list[SearchResult]: diff --git a/app/services/search_service.py b/app/services/search_service.py index 34cba5c..0805c40 100644 --- a/app/services/search_service.py +++ b/app/services/search_service.py @@ -78,7 +78,7 @@ class NewSearchService: logger.warning(f"No content returned for {site_key}") return [] - return NewSearchService._parse_results(html_content, site_key, search_url) + return NewSearchService._parse_results(html_content, site_key, search_url, query) @staticmethod async def scrape_item(result: SearchResult) -> SearchResult: @@ -153,113 +153,73 @@ class NewSearchService: return result @staticmethod - async def search_site(site_key: str, query: str) -> list[SearchResult]: - """Search a single site""" - config = SITE_CONFIGS.get(site_key) - if not config: - logger.error(f"Unknown site: {site_key}") - return [] - - search_url = config["search_url"].format(query=quote_plus(query)) - logger.info(f"Searching {config['name']} at {search_url}") - - # Use proxy if required by config - use_proxy = config.get("requires_proxy", False) - - html_content, _ = await browserless_service.get_page_content( - search_url, - use_proxy=use_proxy, - wait_selector=config.get("wait_selector") - ) - - if not html_content: - logger.warning(f"No content returned for {site_key}") - return [] - - # Phase 1: Parse results - initial_results = NewSearchService._parse_results(html_content, site_key, search_url, query) - - # Phase 2: Scrape details for each result (Parallel) - # Limit concurrency to avoid overloading - semaphore = asyncio.Semaphore(3) - - async def scrape_with_limit(res): - async with semaphore: - return await NewSearchService.scrape_item(res) - - tasks = [scrape_with_limit(r) for r in initial_results] - enriched_results = await asyncio.gather(*tasks) - - return enriched_results - - @staticmethod - def _parse_results(html: str, site_key: str, base_url: str, query: str) -> list[SearchResult]: + def _parse_results(content: str, site: str, base_url: str, query: str) -> list[SearchResult]: """Parse HTML content to extract search results""" - config = SITE_CONFIGS[site_key] - soup = BeautifulSoup(html, "html.parser") results = [] + config = SITE_CONFIGS[site] + soup = BeautifulSoup(content, "html.parser") + + # Log content length and selector + logger.debug(f"Parsing content for {site} (length: {len(content)}) with selector: {config['product_selector']}") - # Prepare query words for filtering - # Split by whitespace, lowercase, remove special chars if needed, filter out short words - query_words = [w.lower() for w in query.split() if len(w) > 2] - - # Select product links links = soup.select(config["product_selector"]) - - # Deduplicate links - seen_urls = set() - - for link in links: - # Limit removed as per user request - # if len(results) >= 5: - # break + logger.debug(f"Found {len(links)} raw items for {site}") - href = link.get("href") + if "amazon" in site: + base_url = "https://www.amazon.fr" + + seen_urls = set() + query_words = query.lower().split() if query else [] + + for container in links: + # Handle container-based selectors (where the selector is the card, not the link) + link = None + href = None + title = None - # Special handling for sites where selector targets a container (Carrefour, Stokomani) + # Try to find link within container + if "product_link_selector" in config: + link_el = container.select_one(config["product_link_selector"]) + if link_el: + link = link_el + href = link.get("href") + + # Fallback: check if container itself is a link + if not href: + href = container.get("href") + if href: + link = container + + # Special handling for sites where selector targets a container but no explicit link selector if not href and config.get("name") in ["Carrefour", "Stokomani"]: - # Try to find the main product link inside the container - # For Carrefour, it's usually .product-card-click-wrapper, but generic 'a' often works if it's the first one - child_link = link.find("a", class_="product-card-click-wrapper") or link.find("a") + child_link = container.find("a", class_="product-card-click-wrapper") or container.find("a") if child_link: href = child_link.get("href") - # Update link to point to the anchor for title/image extraction link = child_link if not href: + # logger.debug(f"Skipping result: No href found for {config['name']}") continue full_url = urljoin(base_url, href) - # Basic cleanup if full_url in seen_urls: continue seen_urls.add(full_url) # Extract title - title = link.get_text(strip=True) + title = None + if "product_title_selector" in config: + # Use container to find title + title_el = container.select_one(config["product_title_selector"]) + if title_el: + title = title_el.get_text(strip=True) - # If no text, check title attribute or nested image alt - if not title: - if link.get("title"): - title = link.get("title") - else: - img = link.find("img") - if img and img.get("alt"): - title = img.get("alt") - - # Special case for Stokomani or similar where link might be wrapping text but get_text failed or we selected a container - if not title and config.get("name") == "Stokomani": - # If we selected the container .product-card__title, the link is inside - child_link = link.find("a") - if child_link: - title = child_link.get_text(strip=True) - if not href: # Update href if we selected a container - href = child_link.get("href") - if href: - full_url = urljoin(base_url, href) + if not title and link: + title = link.get_text(strip=True) if not title or len(title) < 3: + logger.debug(f"Skipping result: No title or too short ({title}) for {full_url}") continue # STRICT FILTERING: Check if all query words are in the title @@ -272,7 +232,7 @@ class NewSearchService: break if not all_words_found: - # logger.debug(f"Skipping result '{title}' - does not contain all query words: {query_words}") + logger.debug(f"Skipping result '{title}' - does not contain all query words: {query_words}") continue # Extract Image URL (Enhanced with multi-selector support) @@ -284,17 +244,10 @@ class NewSearchService: img_el = None # Try each selector in order for selector in selectors: - # Search in the link itself first - img_el = link.select_one(selector) + # Search in the container first + img_el = container.select_one(selector) if img_el: break - - # If not found in link, search in parent container - container = link.find_parent("article") or link.find_parent("div", class_=lambda x: x and "product" in x) - if container: - img_el = container.select_one(selector) - if img_el: - break if img_el: # Try multiple image attributes in order of priority @@ -311,9 +264,9 @@ class NewSearchService: srcset = img_el.get("srcset") image_url = srcset.split(",")[0].split()[0] - # Fallback: Find any img in the link + # Fallback: Find any img in the container if not image_url: - img = link.find("img") + img = container.find("img") if img: image_url = ( img.get("src") or @@ -328,35 +281,18 @@ class NewSearchService: srcset = img.get("srcset") image_url = srcset.split(",")[0].split()[0] - # Fallback: Search in parent container - if not image_url: - container = link.find_parent("article") or link.find_parent("div", class_=lambda x: x and "product" in x) - if container: - img = container.find("img") - if img: - image_url = ( - img.get("src") or - img.get("data-src") or - img.get("data-lazy-src") or - img.get("data-original") or - img.get("data-lazy") - ) - if not image_url and img.get("srcset"): - srcset = img.get("srcset") - image_url = srcset.split(",")[0].split()[0] - # Make absolute URL if image_url: # Clean up data URIs or invalid URLs if image_url.startswith("data:"): - logger.debug(f"Skipping data URI for: {title[:30]}") + # logger.debug(f"Skipping data URI for: {title[:30]}") image_url = None elif not image_url.startswith("http"): image_url = urljoin(base_url, image_url) # Log if image not found if not image_url: - logger.warning(f"No image found for: {title[:50]} | {site_key}") + logger.warning(f"No image found for: {title[:50]} | {site}") # Create result @@ -368,7 +304,7 @@ class NewSearchService: image_url=image_url )) - logger.info(f"Found {len(results)} results for {site_key}") + logger.info(f"Found {len(results)} results for {site}") return results @staticmethod diff --git a/check_import.py b/check_import.py new file mode 100644 index 0000000..8adb705 --- /dev/null +++ b/check_import.py @@ -0,0 +1,12 @@ +import sys +import os +sys.path.append(os.path.abspath(os.path.join(os.path.dirname(__file__), "."))) +import app.core.search_config +print(f"Search Config File: {app.core.search_config.__file__}") +from app.core.search_config import SITE_CONFIGS +print(f"Keys: {list(SITE_CONFIGS.keys())}") + +with open(app.core.search_config.__file__, 'r') as f: + content = f.read() + print(f"File content length: {len(content)}") + print(f"Contains stokomani.fr: {'stokomani.fr' in content}") diff --git a/debug_search.py b/debug_search.py new file mode 100644 index 0000000..3d447aa --- /dev/null +++ b/debug_search.py @@ -0,0 +1,54 @@ +import asyncio +import logging +import sys +import os + +# Add project root to path +sys.path.append(os.path.abspath(os.path.join(os.path.dirname(__file__), "."))) + +from app.services.search_service import new_search_service +from app.services.browserless_service import browserless_service +from app.core.search_config import SITE_CONFIGS + +# Configure logging +logging.basicConfig( + level=logging.INFO, + format="%(asctime)s - %(name)s - %(levelname)s - %(message)s", + handlers=[logging.StreamHandler()] +) + +async def debug_search(): + print("--- Debugging Search ---") + + # Check Config + print(f"Available Config Keys: {list(SITE_CONFIGS.keys())}") + + sites = ["amazon.fr", "stokomani.fr", "lincroyable.fr"] + query = "iphone" + + try: + await browserless_service.initialize() + + for site in sites: + print(f"\nTesting {site}...") + if site not in SITE_CONFIGS: + print(f"❌ Site {site} NOT found in SITE_CONFIGS") + continue + + try: + count = 0 + async for r in new_search_service.search_site_generator(site, query): + count += 1 + print(f"✅ Found: {r.title} - {r.price} {r.currency}") + if count >= 1: + break + if count == 0: + print(f"⚠️ No results for {site}") + except Exception as e: + print(f"❌ Error searching {site}: {e}") + + finally: + await browserless_service.shutdown() + +if __name__ == "__main__": + asyncio.run(debug_search()) diff --git a/inspect_lincroyable.py b/inspect_lincroyable.py new file mode 100644 index 0000000..a514b9c --- /dev/null +++ b/inspect_lincroyable.py @@ -0,0 +1,28 @@ +import asyncio +import logging +import sys +import os + +# Add project root to path +sys.path.append(os.path.abspath(os.path.join(os.path.dirname(__file__), "."))) + +from app.services.browserless_service import browserless_service + +# Configure logging +logging.basicConfig(level=logging.INFO) + +async def inspect(): + url = "https://www.lincroyable.fr/recherche-query=iphone/" + print(f"Inspecting {url}...") + + await browserless_service.initialize() + try: + content, _ = await browserless_service.get_page_content(url, wait_selector="body") + with open("lincroyable_dump.html", "w", encoding="utf-8") as f: + f.write(content) + print("HTML dumped to lincroyable_dump.html") + finally: + await browserless_service.shutdown() + +if __name__ == "__main__": + asyncio.run(inspect()) diff --git a/inspect_sites.py b/inspect_sites.py new file mode 100644 index 0000000..6b02d7d --- /dev/null +++ b/inspect_sites.py @@ -0,0 +1,47 @@ +import asyncio +import logging +from app.services.browserless_service import BrowserlessService +from app.core.search_config import SITE_CONFIGS + +# Configure logging +logging.basicConfig(level=logging.INFO) +logger = logging.getLogger(__name__) + +async def dump_site(site_key, query="chaise"): + config = SITE_CONFIGS.get(site_key) + if not config: + logger.error(f"Site {site_key} not found in config") + return + + search_url = config["search_url"].format(query=query) + logger.info(f"Dumping {site_key} from {search_url}") + + try: + content, _ = await BrowserlessService.get_page_content( + search_url, + wait_selector=config.get("wait_selector"), + use_proxy=config.get("requires_proxy", False) + ) + + if content: + filename = f"/app/{site_key}_dump.html" + with open(filename, "w", encoding="utf-8") as f: + f.write(content) + logger.info(f"Successfully dumped to {filename}") + else: + logger.error(f"Failed to get content for {site_key}") + + except Exception as e: + logger.error(f"Error dumping {site_key}: {e}") + +async def main(): + await BrowserlessService.initialize() + try: + await dump_site("amazon.fr") + await dump_site("stokomani.fr") + # await dump_site("lincroyable.fr") # Already have this + finally: + await BrowserlessService.shutdown() + +if __name__ == "__main__": + asyncio.run(main()) diff --git a/lincroyable_dump.html b/lincroyable_dump.html new file mode 100644 index 0000000..6eb961b --- /dev/null +++ b/lincroyable_dump.html @@ -0,0 +1,1842 @@ + + + + + + + + iphone - L'Incroyable + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + +
+
+ + + + + + + + + + + + + +
+ +
+
+
+

Recherche

26 résultats pour votre recherche "iphone"

+ +
+
+ +
+
+
+ + + +
+
+ +
+
+ +
+
+

coup de coeur

+

+
+
+ Chaise Florence + plusieurs gammes
+ +
+ +
+

Chaise Florence

+

En polypropylène
+

44.5x42/48.5xh.79cm

+

29€99

+ +
+ +

Ajouter au panier

+
+
+
+
+
+

coup de coeur

+

+
+
+ Chaise Florence + plusieurs gammes
+ +
+ +
+

Chaise Florence

+

En polypropylène
+

44.5x42/48.5xh.79cm

+

29€99

+ +
+ +

Ajouter au panier

+
+
+
+
+
+

coup de coeur

+

+
+
+ Poêle + plusieurs gammes
+3
+ +
+ +
+

Poêle 'Metallic' induction

+

En aluminium
+

d28cm

+

14€99

+ +
+ +

Uniquement en magasin

+
+
+
+
+
+

coup de coeur

+

+
+
+ Poêle + plusieurs gammes
+3
+ +
+ +
+

Poêle 'Metallic' induction

+

En aluminium
+

d30cm

+

16€99

+ +
+ +

Uniquement en magasin

+
+
+
+ +
+
+

coup de coeur

+

+
+
+ Poêle + plusieurs gammes
+3
+ +
+ +
+

Poêle 'Metallic' induction

+

En aluminium
+

d26cm

+

13€99

+ +
+ +

Uniquement en magasin

+
+
+
+
+
+

coup de coeur

+

+
+
+ Bac de rangement + plusieurs gammes
+ +
+ +
+

Bac de rangement 'Estanca' 75L gris

+

Certifié IP67
+

64x47xh33.3cm

+

24€99

+ +
+ +

Ajouter au panier

+
+
+
+
+
+

coup de coeur

+

+
+
+ Bac de rangement + plusieurs gammes
+ +
+ +
+

Bac de rangement 'Estanca' 75L

+

Certifié IP67
+

64x47xh33.3cm

+

24€99

+ +
+ +

Ajouter au panier

+
+
+
+ +
+
+

coup de coeur

+

+
+
+ Bac de rangement + plusieurs gammes
+ +
+ +
+

Bac de rangement 'Estanca' 50L

+

Certifié IP67
+

57.8x38.2xh31.8cm

+

17€99

+ +
+ +

Ajouter au panier

+
+
+
+
+
+
+
+ retour Top +
+
+ +
+ + + + + + + + + + + + + + + + + + + + + + + + +
\ No newline at end of file diff --git a/reset_admin.py b/reset_admin.py new file mode 100644 index 0000000..c99f940 --- /dev/null +++ b/reset_admin.py @@ -0,0 +1,31 @@ +from app.database import SessionLocal +from app.services import auth_service +from app import models + +def reset_admin(): + db = SessionLocal() + try: + user = auth_service.get_user_by_username(db, "admin") + if user: + print("Found admin user. Resetting password...") + auth_service.update_password(db, user, "admin") + print("Password reset to 'admin'") + + # Verify + print("Verifying login...") + auth_user = auth_service.authenticate_user(db, "admin", "admin") + if auth_user: + print("SUCCESS: Login verified!") + else: + print("ERROR: Login failed after reset!") + else: + print("Admin user not found. Creating...") + auth_service.create_user(db, "admin", "admin", is_admin=True) + print("Admin user created with password 'admin'") + except Exception as e: + print(f"Error: {e}") + finally: + db.close() + +if __name__ == "__main__": + reset_admin() diff --git a/stokomani.fr_dump.html b/stokomani.fr_dump.html new file mode 100644 index 0000000..837301c --- /dev/null +++ b/stokomani.fr_dump.html @@ -0,0 +1,18100 @@ + + + + + + + + + Recherche : 31 résultats trouvés pour « chaise » – Stokomani + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + Passer au contenu +
+ +
+ +
+
+ + +
+
+
+ + +
+
+
+ +
+ + +
+
+
+ +
+
+ +
+
+
+
+ +
+
+
+ + + +
+ + +
+
+ + + + + + + +
+
+ + + + +
+ + +
+
+ +
+
+ + + + + + + + + + + + + + + +
+ + +
+ + + + + + + +
+ + +
+ +
\ No newline at end of file diff --git a/stokomani.fr_failed_verification.html b/stokomani.fr_failed_verification.html new file mode 100644 index 0000000..c7dbbe9 --- /dev/null +++ b/stokomani.fr_failed_verification.html @@ -0,0 +1,18100 @@ + + + + + + + + + Recherche : 31 résultats trouvés pour « chaise » – Stokomani + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + Passer au contenu +
+ +
+ +
+
+ + +
+
+
+ + +
+
+
+ +
+ + +
+
+
+ +
+
+ +
+
+
+
+ +
+
+
+ + + +
+ + +
+
+ + + + + + + +
+
+ + + + +
+ + +
+
+ +
+
+ + + + + + + + + + + + + + + +
+ + +
+ + + + + + + +
+ + +
+ +
\ No newline at end of file diff --git a/test_soup.py b/test_soup.py new file mode 100644 index 0000000..3df7bef --- /dev/null +++ b/test_soup.py @@ -0,0 +1,29 @@ +from bs4 import BeautifulSoup +import sys + +try: + with open("/app/debug_dumps/stokomani.fr_failed_verification.html", "r", encoding="utf-8") as f: + content = f.read() + + print(f"Read {len(content)} bytes") + + soup = BeautifulSoup(content, "html.parser") + print("Soup created") + + selector = "div.product-card" + items = soup.select(selector) + print(f"Found {len(items)} items with selector '{selector}'") + + if items: + item = items[0] + print("First item classes:", item.get("class")) + + title_selector = "h3.product-card__title a" + title_el = item.select_one(title_selector) + if title_el: + print("Title found:", title_el.get_text(strip=True)) + else: + print(f"Title NOT found with '{title_selector}'") + +except Exception as e: + print(f"Error: {e}") diff --git a/verify_all_sites.py b/verify_all_sites.py index 444bc5a..b891aba 100644 --- a/verify_all_sites.py +++ b/verify_all_sites.py @@ -1,147 +1,69 @@ -""" -Script de vérification complète du comparateur sur tous les sites configurés -""" import asyncio import logging -import sys -import os -from datetime import datetime - -# Add project root to path -sys.path.append(os.path.abspath(os.path.join(os.path.dirname(__file__), "."))) - +import time +from app.services.improved_search_service import ImprovedSearchService from app.core.search_config import SITE_CONFIGS -from app.services.search_service import new_search_service -from app.services.browserless_service import browserless_service # Configure logging -logging.basicConfig( - level=logging.INFO, - format="%(asctime)s - %(name)s - %(levelname)s - %(message)s", - handlers=[logging.StreamHandler()] -) - +logging.basicConfig(level=logging.INFO, format='%(asctime)s - %(levelname)s - %(message)s') logger = logging.getLogger(__name__) -async def test_site(site_key: str, query: str) -> dict: - """Test a single site and return results""" - config = SITE_CONFIGS[site_key] - result = { - "site": config["name"], - "site_key": site_key, - "category": config["category"], - "success": False, - "count": 0, - "error": None, - "sample_results": [] - } +async def verify_site(site_key: str): + print(f"\n{'='*50}") + print(f"🔍 Verifying {site_key}...") + print(f"{'='*50}") + + start_time = time.time() + first_result_time = None + count = 0 try: - print(f"\n🔍 Testing {config['name']} ({site_key})...") - results = await new_search_service.search_site(site_key, query) - - if results: - result["success"] = True - result["count"] = len(results) - # Store first 2 results as samples - result["sample_results"] = [ - { - "title": r.title, - "url": r.url, - "price": r.price, - "in_stock": r.in_stock - } - for r in results[:2] - ] - print(f" ✅ Found {len(results)} results") - for r in results[:2]: - price_str = f"{r.price}€" if r.price else "N/A" - stock_str = "✓" if r.in_stock else "✗" if r.in_stock is False else "?" - print(f" - {r.title[:60]}... [{price_str}] [Stock: {stock_str}]") - else: - print(f" ⚠️ No results found") + async for result in ImprovedSearchService.search_site_generator(site_key, "chaise"): + count += 1 + if count == 1: + first_result_time = time.time() + elapsed = first_result_time - start_time + print(f"🚀 First result in {elapsed:.2f}s") + print(f" Title: {result.title}") + print(f" Price: {result.price} {result.currency}") + print(f" Image: {result.image_url}") - except Exception as e: - result["error"] = str(e) - print(f" ❌ Error: {e}") - logger.exception(f"Error testing {site_key}") - - return result + # Print a dot for each result to show progress + print(".", end="", flush=True) + + total_time = time.time() - start_time + print(f"\n✅ Finished {site_key}: {count} results in {total_time:.2f}s") + + if count == 0: + print(f"❌ WARNING: 0 results found for {site_key}") + return False + return True -async def verify_all_sites(): - """Test all configured sites""" - query = "chaise" # Test query - - print("=" * 80) - print(f"VERIFICATION DU COMPARATEUR - Query: '{query}'") - print(f"Started at: {datetime.now().strftime('%Y-%m-%d %H:%M:%S')}") - print("=" * 80) - - # 1. Test Browserless Connection - print("\n[1] Testing Browserless Connection...") - try: - await browserless_service.initialize() - print("✅ Browserless connected successfully") except Exception as e: - print(f"❌ Browserless connection failed: {e}") - return + print(f"\n❌ ERROR verifying {site_key}: {e}") + return False + +async def main(): + await ImprovedSearchService.initialize() - # 2. Test all sites - print(f"\n[2] Testing {len(SITE_CONFIGS)} configured sites...") + sites = list(SITE_CONFIGS.keys()) + results = {} - all_results = [] - for site_key in SITE_CONFIGS.keys(): - result = await test_site(site_key, query) - all_results.append(result) - # Small delay between sites to avoid overload - await asyncio.sleep(1) + # Test all sites sequentially to avoid overwhelming the browser/network + for site in sites: + success = await verify_site(site) + results[site] = success + # Small pause between sites + await asyncio.sleep(2) + + await ImprovedSearchService.shutdown() - # 3. Summary - print("\n" + "=" * 80) + print("\n" + "="*50) print("SUMMARY") - print("=" * 80) - - successful = [r for r in all_results if r["success"]] - failed = [r for r in all_results if not r["success"]] - - print(f"\n✅ Successful: {len(successful)}/{len(all_results)}") - for r in successful: - print(f" - {r['site']:20s} | {r['count']:2d} results | Category: {r['category']}") - - if failed: - print(f"\n❌ Failed: {len(failed)}/{len(all_results)}") - for r in failed: - error_msg = r['error'][:50] if r['error'] else "No results" - print(f" - {r['site']:20s} | Error: {error_msg}") - - # 4. Detailed results by category - print("\n" + "=" * 80) - print("BY CATEGORY") - print("=" * 80) - - categories = {} - for r in all_results: - cat = r["category"] - if cat not in categories: - categories[cat] = [] - categories[cat].append(r) - - for cat, sites in categories.items(): - successful_count = sum(1 for s in sites if s["success"]) - print(f"\n{cat}: {successful_count}/{len(sites)} working") - for site in sites: - status = "✅" if site["success"] else "❌" - count = f"({site['count']} results)" if site["success"] else "(failed)" - print(f" {status} {site['site']:20s} {count}") - - # 5. Cleanup - await browserless_service.shutdown() - - print("\n" + "=" * 80) - print(f"Verification completed at: {datetime.now().strftime('%Y-%m-%d %H:%M:%S')}") - print("=" * 80) - - return all_results + print("="*50) + for site, success in results.items(): + status = "✅ PASS" if success else "❌ FAIL" + print(f"{status} - {site}") if __name__ == "__main__": - asyncio.run(verify_all_sites()) + asyncio.run(main()) diff --git a/verify_new_search.py b/verify_new_search.py index 1fa16c0..f969e52 100644 --- a/verify_new_search.py +++ b/verify_new_search.py @@ -8,45 +8,66 @@ sys.path.append(os.path.abspath(os.path.join(os.path.dirname(__file__), "."))) from app.services.search_service import new_search_service from app.services.browserless_service import browserless_service +from app.core.search_config import SITE_CONFIGS # Configure logging logging.basicConfig( - level=logging.INFO, + level=logging.DEBUG, # Enable DEBUG logging format="%(asctime)s - %(name)s - %(levelname)s - %(message)s", handlers=[logging.StreamHandler()] ) +# Set other loggers to INFO to avoid noise +logging.getLogger("urllib3").setLevel(logging.INFO) +logging.getLogger("asyncio").setLevel(logging.INFO) +logging.getLogger("websockets").setLevel(logging.INFO) async def verify_search(): - query = "iphone 15" + query = "chaise" # Updated query print(f"--- Starting Verification Search for '{query}' ---") # 1. Test Browserless Connection print("\n[1] Testing Browserless Connection...") try: - await browserless_service.start() + await browserless_service.initialize() print("✅ Browserless connected successfully") except Exception as e: print(f"❌ Browserless connection failed: {e}") return # 2. Test Specific Sites - sites_to_test = ["gifi.fr", "amazon.fr", "e.leclerc"] + # sites_to_test = ["gifi.fr", "lincroyable.fr", "stokomani.fr"] # Excluded amazon.fr + sites_to_test = ["stokomani.fr"] # Focus on Stokomani for now as requested/implied context for site in sites_to_test: print(f"\n[2] Testing Search on {site}...") try: - results = await new_search_service.search_site(site, query) - if results: - print(f"✅ Found {len(results)} results for {site}") - for r in results[:2]: - print(f" - {r.title} ({r.url})") - else: + count = 0 + async for r in new_search_service.search_site_generator(site, query): + count += 1 + print(f"✅ Found result: {r.title} ({r.url})") + print(f" Price: {r.price} {r.currency}") + print(f" Image: {r.image_url}") + if count >= 1: + break + if count == 0: print(f"⚠️ No results found for {site}") + # Dump HTML for debugging + try: + content, _ = await browserless_service.get_page_content( + SITE_CONFIGS[site]["search_url"].format(query=query), + use_proxy=SITE_CONFIGS[site].get("requires_proxy", False), + wait_selector=SITE_CONFIGS[site].get("wait_selector") + ) + with open(f"/app/debug_dumps/{site}_failed_verification.html", "w", encoding="utf-8") as f: + f.write(content) + print(f"📄 Saved HTML dump to /app/debug_dumps/{site}_failed_verification.html") + except Exception as dump_e: + print(f"❌ Failed to save HTML dump: {dump_e}") except Exception as e: print(f"❌ Error searching {site}: {e}") # 3. Cleanup - await browserless_service.stop() + await browserless_service.shutdown() print("\n--- Verification Complete ---") if __name__ == "__main__":